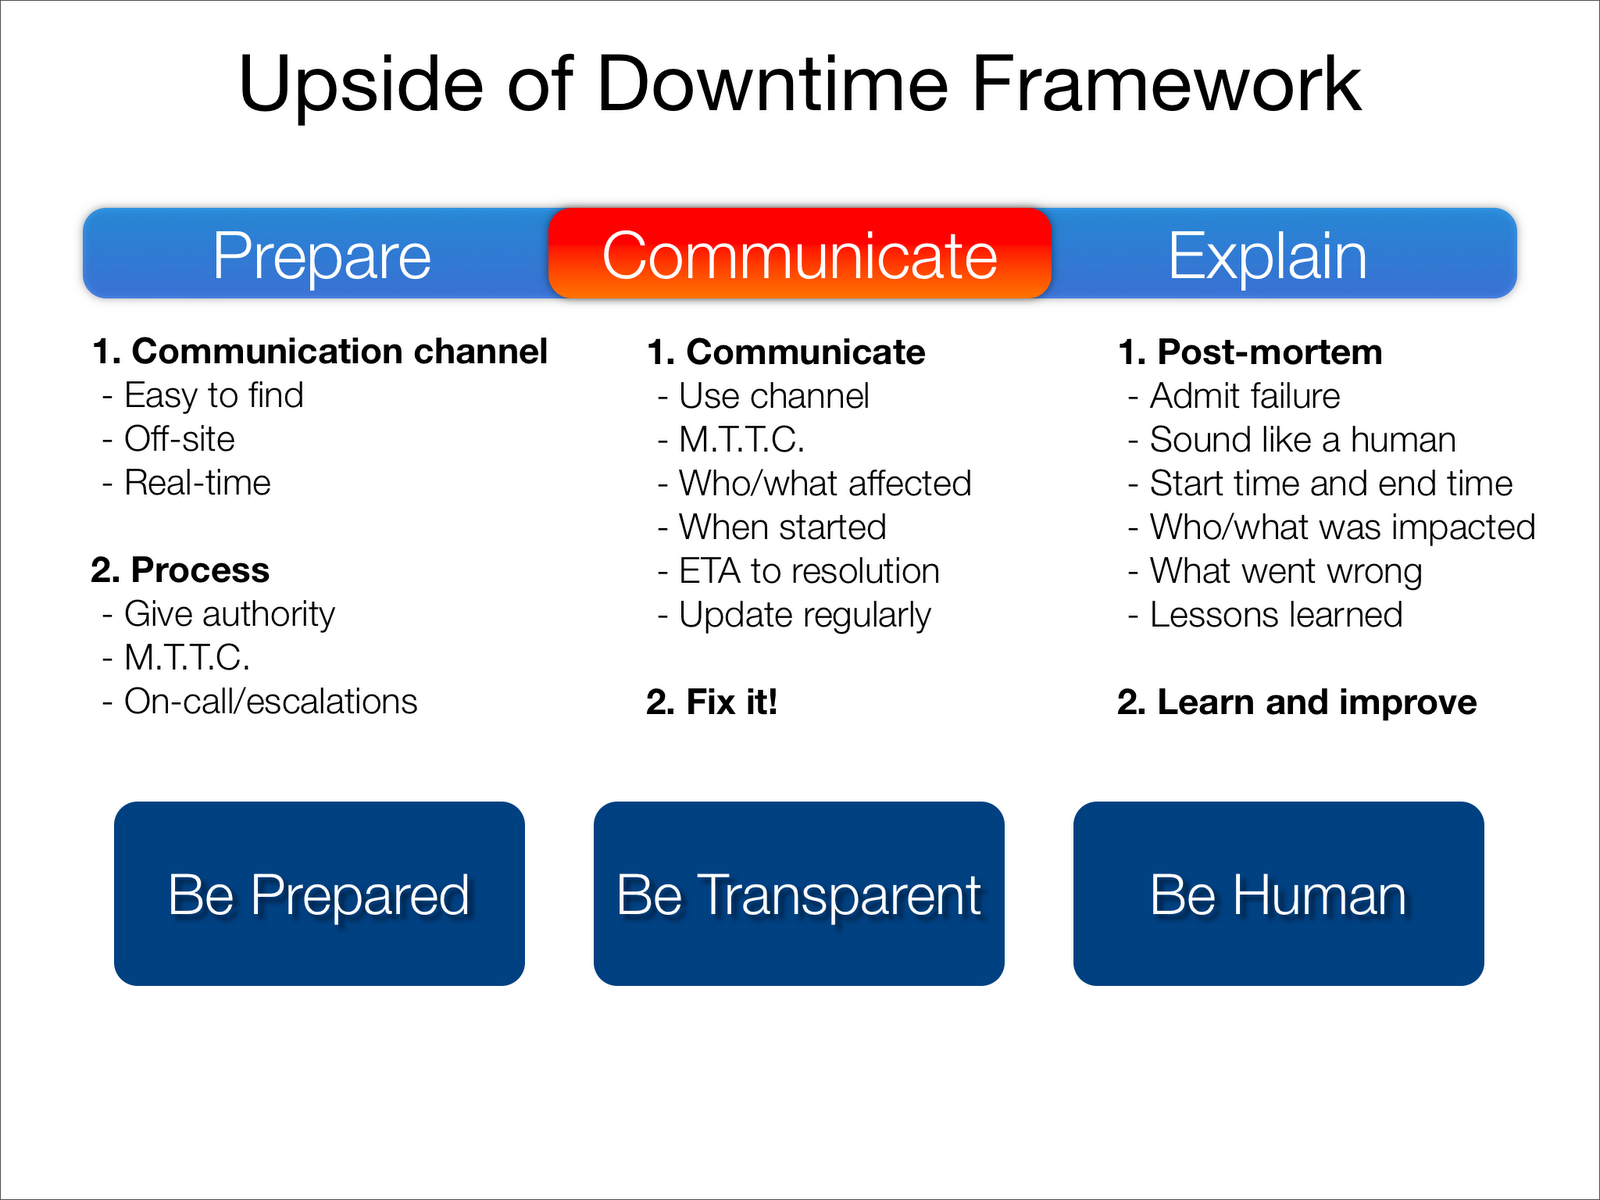
I'm looking forward to see how many of the rules of successful health status dashboards they follow!
 As widely reported by the blogosphere, Gmail was down earlier today for anywhere from 2 to 4 hours. Panic did not ensue...except on Twitter. Plenty has been said about the downtime event (and the demise of the cloud thanks to events like this). I want to focus on my favorite topic...how transparent was Google, and did they use this opportunity to build longer term trust in their service? Let's read a few select quotes that I found most illuminating:
What's more disturbing than the Gmail outage is Google's lack of transparency about it. The most recent post on Google's official blog declares the problem over, apologizes for the inconvenience, and explains why some users had to prove to Google that they were human beings before being allowed to log in to their Gmail accounts. But it provides no explanation whatever of what went wrong or what had been done to fix it or prevent its recurrence.Technologizer:
Amazon, by contrast, maintains a Service Health Dashboard for its Amazon Web Services with both a report on the current status of each service and a 35-day history of any problems (I can't tell you how good the reports are because the current time frame shows no incidents.) At a minimum, Google should maintain a similar site for the folks who have come to depend on its services.
Google has apologized and says it isn’t yet sure what happened: I’d love to see the company follow up with a post discussing the outage, its cause, and the company’s response. I’m curious, for instance, whether there’s a single explanation for the multiple problems that the service has had in the past few months.ComputerWorld:
Finally, it may not hurt to have a few links to the Google Blog and Gmail Blog on your Intranet so that they can find out if something catastrophic is happening. One of my users was smart enough to do this and alert the office.VentureBeat:
Almost everyone I follow on Twitter seems to use Gmail. At all points during the outage, almost my entire stream was consumed with tweets about Gmail being down. And Twitter Search, perhaps the ultimate search engine for what people are complaining about in real time, not only had the term “Gmail” as a trending topic of discussions within minutes of Gmail failing, but it also saw “IMAP” and “Gfail” rise into the top terms as well.Conclusion: Not enough transparency. Twitter again is the only means users had to share what was going on. Google's blog post was nice, but not enough to sate most people. I'm hoping Google comes out with a more detailed analysis, if nothing else to show that they are really trying.
I remember a few years back when my company’s email went down - for days, not hours. It would come back and then go away again as the IT team worked to troubleshoot and fix the problem. The folks working on that IT team weren’t necessarily e-mail experts, though. They were charged with doing everything from upgrading software to configuring network settings. Troubleshooting email was just another job duty.
I still maintain that a cloud-based solution - whether Google’s or anyone else’s - is a more efficient way of running a business. Don’t let one outage - no matter how widespread - tarnish your opinion of a cloud solution. Outages happen both in the cloud and at the local client level. And having been through a days-long outage, I’d say that this restore time was pretty quick.
One final thought: who out there communicates by e-mail alone these days? Speaking for myself, I’m reachable on Twitter, Facebook, SMS text, and Yahoo IM - among other services. Increasingly, e-mail isn’t as business critical as it once was. If you need to communicate with people to get the job done, I’m sure you can think of at least one other way to keep those communications alive beyond just e-mail.
Yes, the outage was bad. But it wasn’t the end of the world.
 A bit off topic, but I just wanted to share a great article over at Wired about the transparency side benefits that may come along as a result of the stimulus package:
With President Obama's signing of the “American Recovery and Reinvestment Act,” better known as our national Hail Mary stimulus bill, billions will be ladled for infrastructure projects ranging from roads to mass transit to rural broadband.Check out http://www.recovery.gov/ and http://www.stimuluswatch.org/ to follow this story.But the law also contains a measure promoting a less-noted type of economic infrastructure: government data. In the name of transparency, all the Fed’s stimulus-spending data will be posted at a new government site, Recovery.gov.
That step may be more than a minor victory for the democracy. It could be a stimulus in and of itself.
The reason, open government advocates argue, is that accessible government information—particularly databases released in machine-readable formats, like RSS, XML, and KML—spawn new business and grease the wheels of the economy. "The data is the infrastructure," in the words of Sean Gorman, the CEO of FortiusOne, a company that builds layered maps around open-source geographic information. For every spreadsheet squirreled away on a federal agency server, there are entrepreneurs like Gorman ready to turn a profit by reorganizing, parsing, and displaying it.
...
The more obvious economic benefits, however, will come from innovations that pop up around freely available data itself. Robinson and three Princeton colleagues argue in a recent Yale Journal of Law and Technology article that the federal government should focus on making as much data available as RSS feeds and XML data dumps, in lieu of spending resources to display the data themselves. “Private actors,” they write, “are better suited to deliver government information to citizens and can constantly create and reshape the tools individuals use to find and leverage public data.”
 Earlier today we saw Media Temple experience intermittent downtime over the course of an hour. The first tweet showed up around 8am PST noting the downtime. At 9:06am Media Temple provided a short message confirming the outage:
So far, not too bad. Though note the broken rule in hosting your status page in the same location as your service. Lesson #1: Host your status page offsite. Let's keep moving with the timeline....At ~8:30AM Pacific Time we started experiencing networking issues at our El Segundo Data Center. We are working closely with them to determine the cause of these issues and will report any findings as they become available.
At this time we appear to be back fully. The tardiness of this update is a direct result of these networking issues.

Now that everything is back up and users are "happy", what else can we learn from this experience?Our engineers have spoken with the engineers at our El Segundo Data Center (EL-IDC3). Here are their findings:
ASN number 47868 was broadcasting invalid BGP data that caused our routers, and a lot of other routers on the internet, to reboot. This invalid BGP data exploited a software bug in our routers. We have applied filters to prevent us from receiving this invalid data.
At this time they are in contact with their vendors to see if there is a firmware update that will address this. You can expect to see network delays and small outages across the internet as other providers try to address this same issue.
 A lot has been said about the problem of trust in the Cloud. Most recently, Ma.gnolia, a social bookmarking service, lost all of its customers data and is in the process of rebuilding (both the service and the data). The naive take-away from this event is to use this as further evidence that the Cloud cannot be trusted. That we're setting ourselves up for disaster down the road with every SaaS service out there. I see this differently. I see this as a key opportunity for the industry to learn from this experience, and to mature. Both through technology (the obvious stuff) and through transparency (the not-so-obvious stuff). Ma.gnolia must be doing something right if the community has been working diligently and collaboratively in restoring the lost data, while waiting for the service to come back online and to use it again.
The bigger Web commerce gets, the bigger the opportunities to mess it up become. Outages and downtimes are inevitable; the trick is minimizing the pain they cause.As we've seen over the past few months, the simplest way to minimize that pain is by letting your customers know what's going on. Before, during, and after. A little transparency goes a long way.
Read more here. What will you come up with?You must post your business plan here on my blog where I expect other people can and will comment on it. I also expect that other people will steal the idea and use it elsewhere. That is the idea. Call this an open source funding environment.
If its a good idea and worth funding, we want it replicated elsewhere. The idea is not just to help you, but to figure out how to help the economy through hard work and ingenuity. If you come up with the idea and get funding, you have a head start. If you execute better than others, you could possibly make money at it. As you will see from the rules below, these are going to be businesses that are mostly driven by sweat equity.